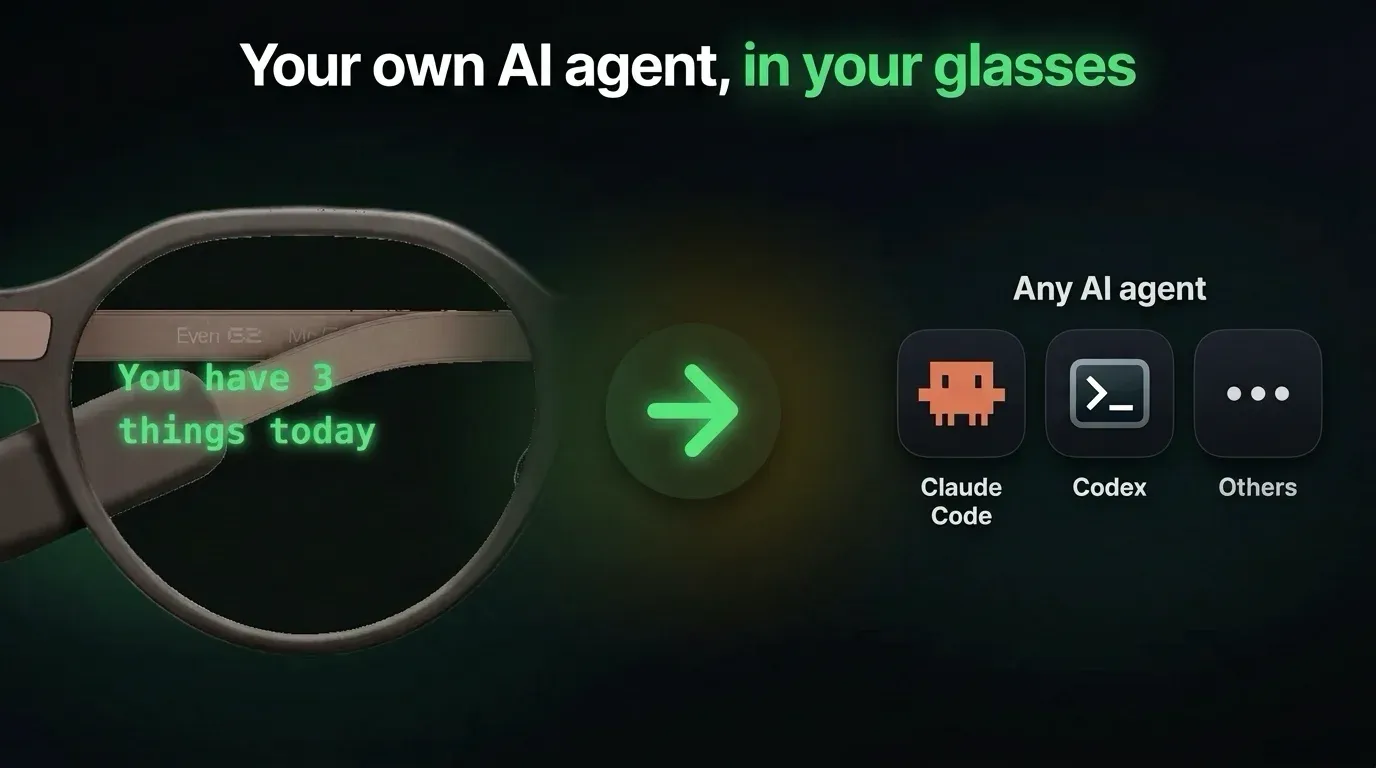
Use your own AI agent as the assistant on your Even Realities glasses
The Even app can send what you say to a URL you control, so your own AI agent can be the assistant on your glasses. How it works, how to set it up, and a sample server.
Any agent that can answer an HTTP request can be the assistant on your glasses.
The Even Realities G2 smart glasses answer “Hey Even” with Even’s built-in assistant. The Even app lets you swap that for your own AI agent: your words go to a URL you control, and what your agent sends back shows up on the lens.
Want an agent to just build this for you? Copy the prompt below and paste it into your AI agent. It tells the agent what to build and sends it back here for the actual instructions.
Prompt for your coding agent▾
I want my Even Realities G2 glasses to answer "Hey Even" with my own AI agent instead of Even's built-in assistant. The Even app can send each spoken request to a URL I control, in OpenAI chat-completions format, and show my server's reply on the lens.

The full instructions, the request and response format, and a sample server are here:

https://strangenewworld.net/use-your-own-ai-agent-as-the-assistant-on-your-even-realities-glasses/

Read that page first, then build it.
⚙️ Requirements
👓 Even Realities G2 glasses, paired to the Even app.
🧑💻 An approved EvenHub developer account. Per Even's own tutorial, the Agent Configuration menu is only visible to EvenHub developers.
🌐 A URL your phone can reach. The app calls exactly the address you type.
🤖 An AI agent or model you can call from a server.
Bring your own agent
Say “Hey Even” and your agent answers on the lens, with whatever tools and memory it has. Mine is Claude Code running on my own server. Here is what that looks like:
“Hey Even, what does Reddit recommend as the best chamomile tea I can order on Amazon Japan?”
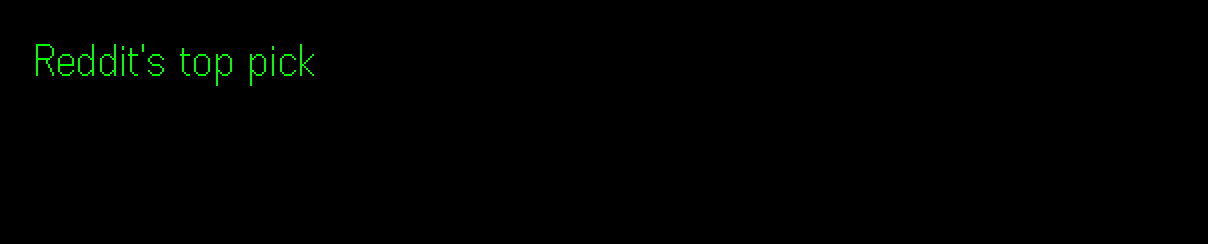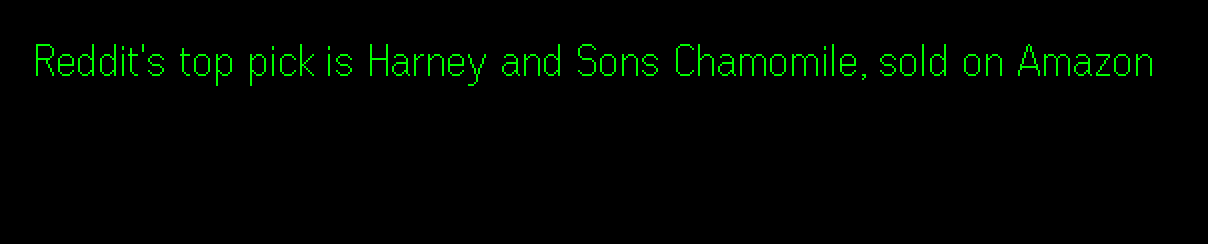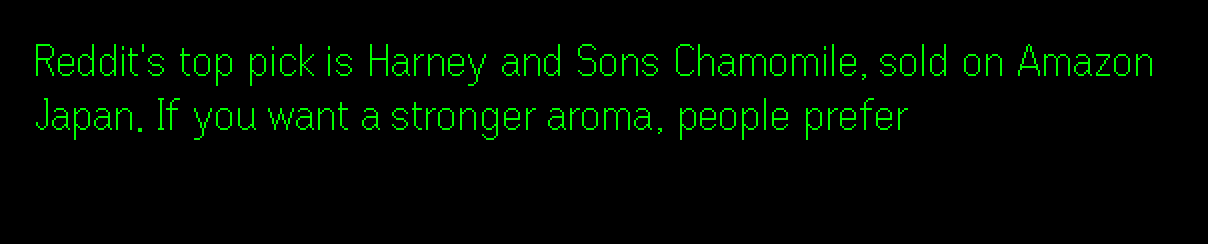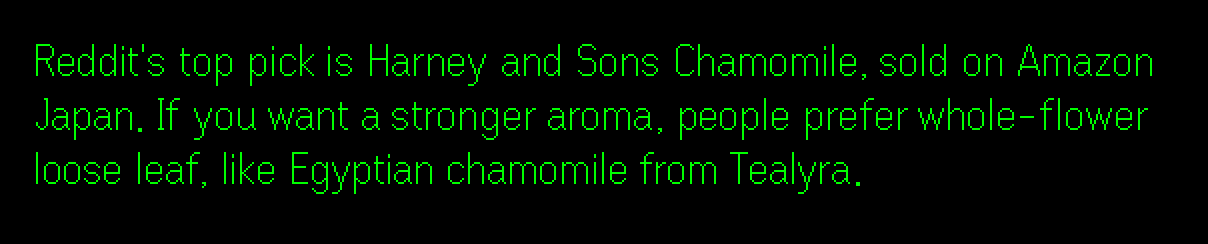
Reddit's top pick is Harney and Sons Chamomile, sold on Amazon Japan. If you want a stronger aroma, people prefer whole-flower loose leaf, like Egyptian chamomile from Tealyra.
The agent searched Reddit threads, read the comments, then matched the winning brands to what Amazon Japan actually sells.
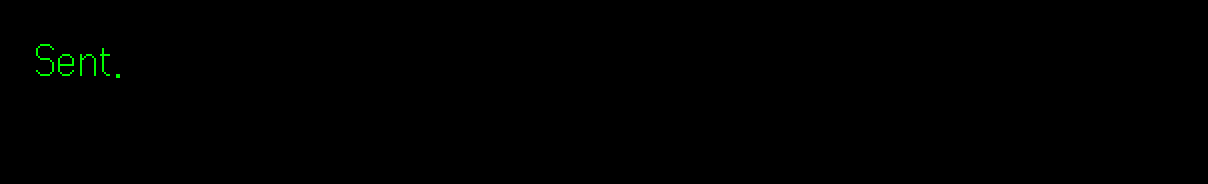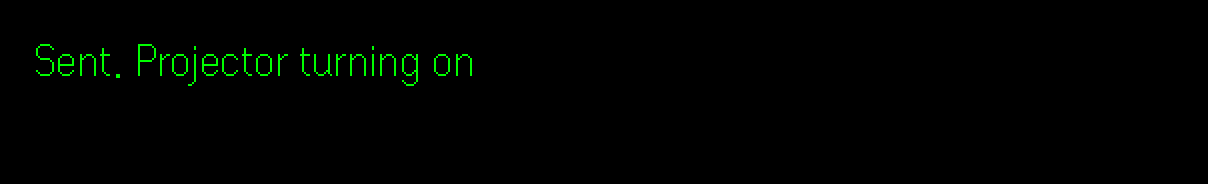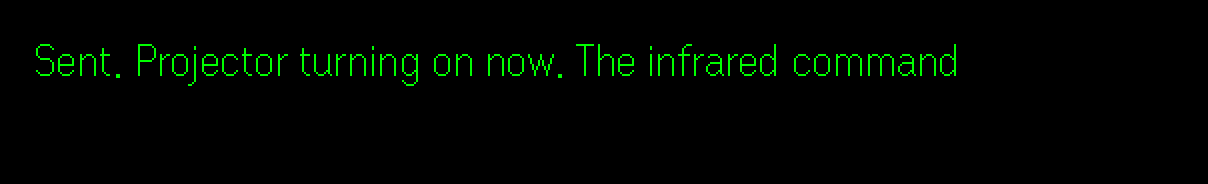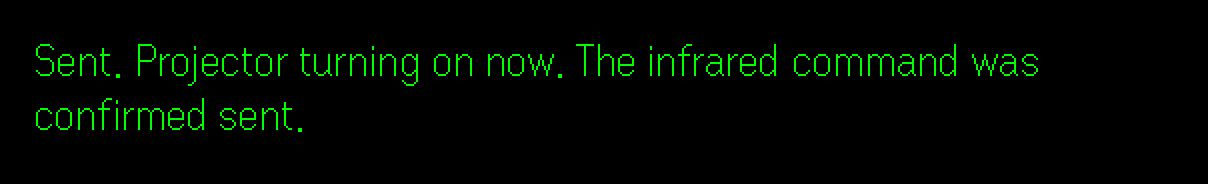
“Hey Even, turn on the projector.”
Sent. Projector turning on now. The infrared command was confirmed sent.
The agent found the right smart-home skill, fired the projector's infrared remote through a hub, and confirmed it went out.
“Hey Even, go and research which of my recurring subscriptions renewed in the last month and put together a summary of what each one costs.”
Started. This one takes a while, so I'll ping you on Telegram when the report is ready.
The agent opened a task, combed through months of payment receipts in my inboxes, and later posted an itemized table to my Telegram while I was walking.
Set it up in the Even app
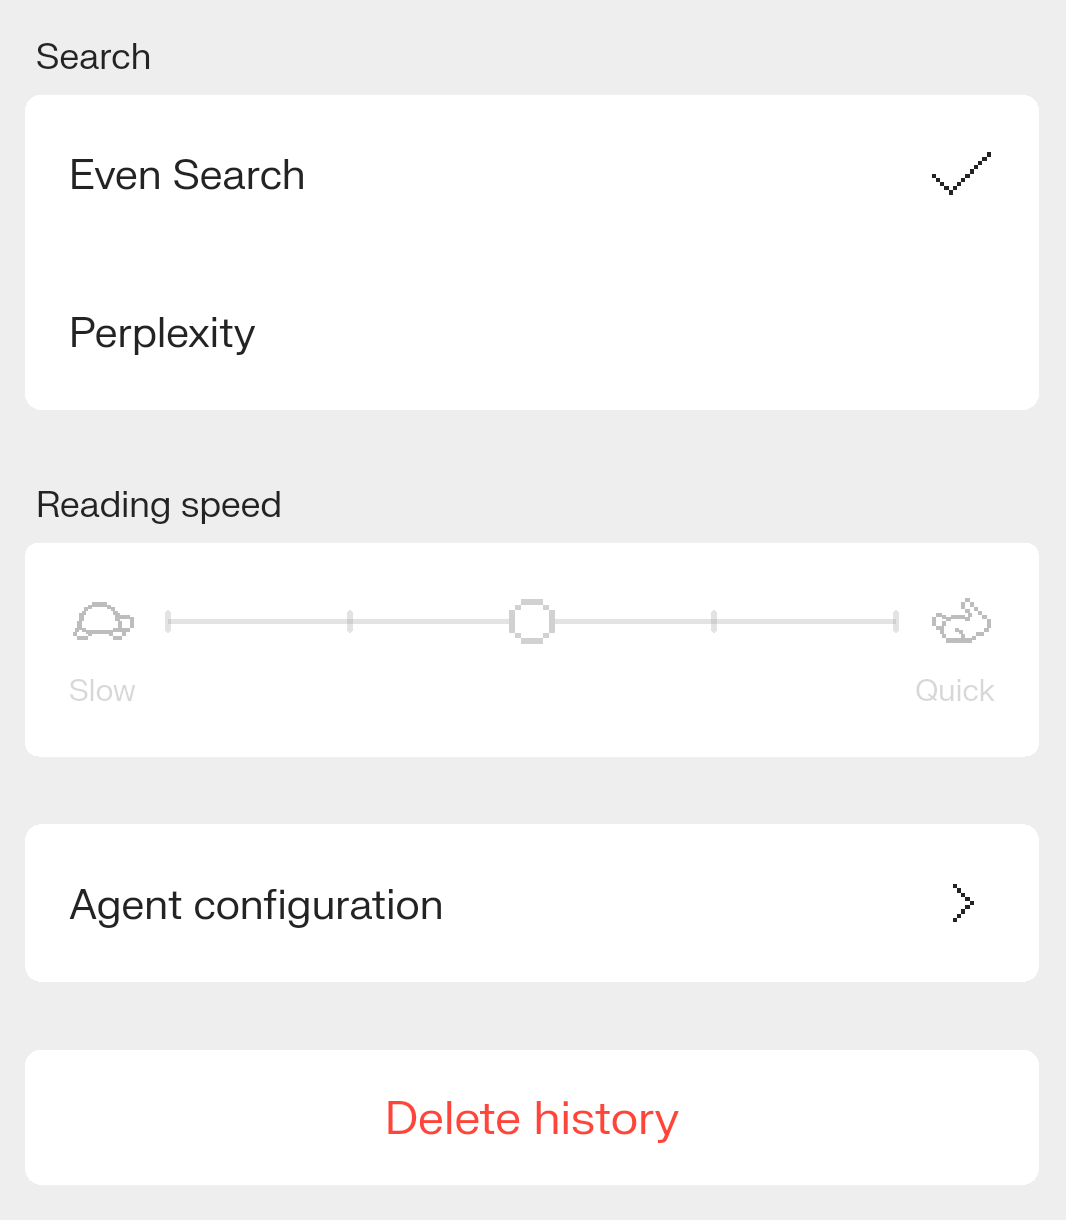
Where it lives: Settings, then Even AI, then Agent configuration.
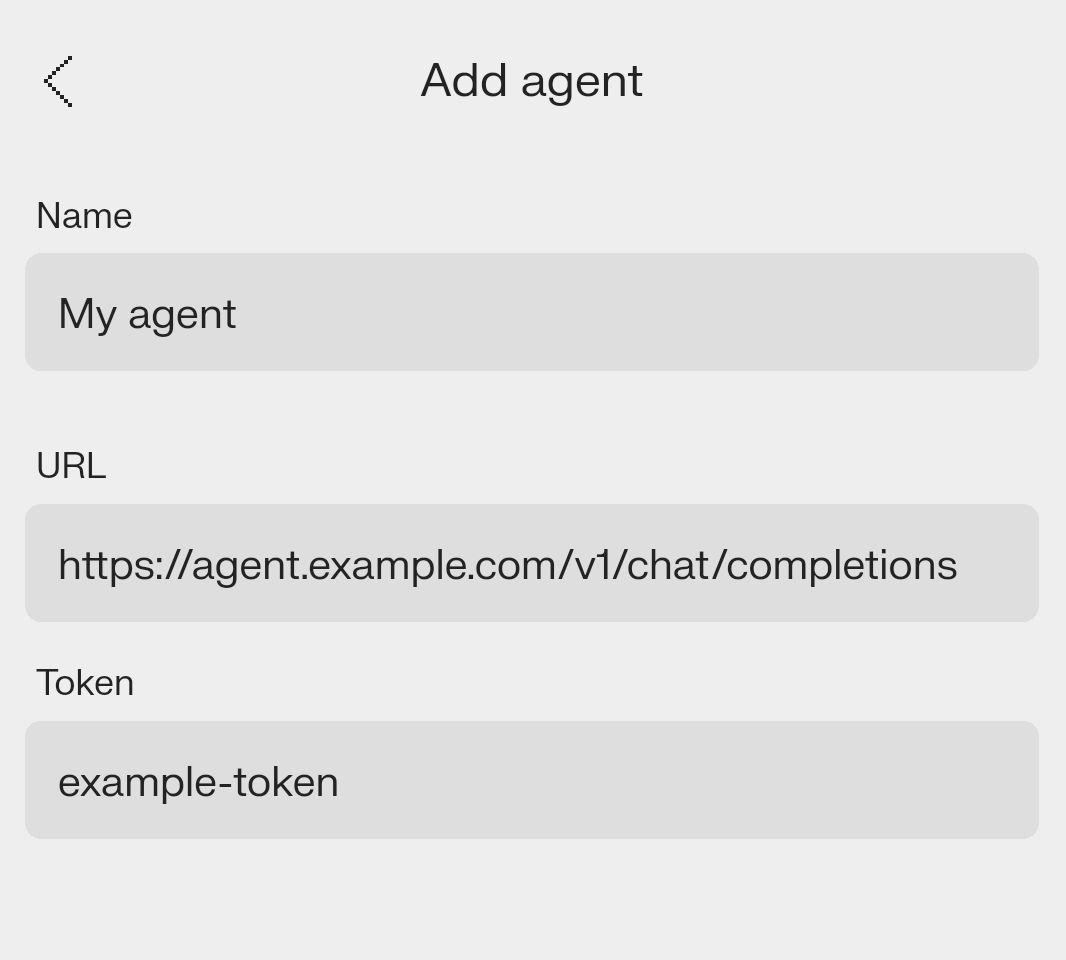
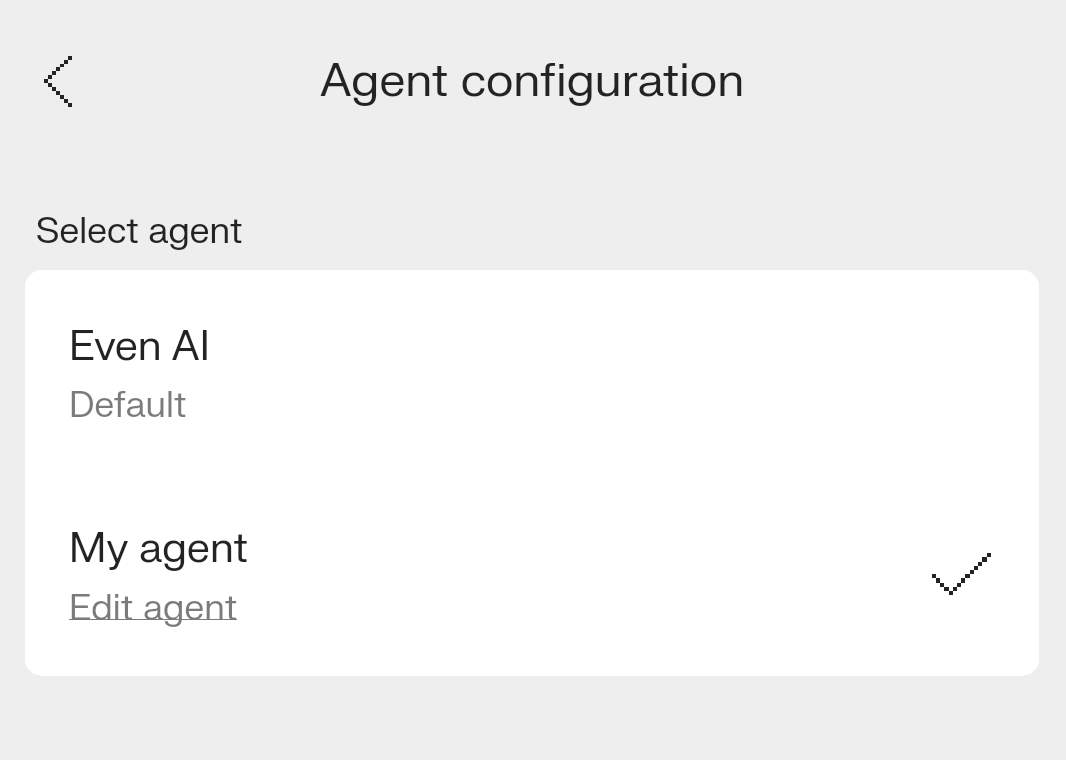
Open Settings, then Even AI, then Agent Configuration, then Add agent. Enter a name, your server’s URL and a token, then tap the agent in the list to select it. Saving alone doesn’t select it.
Even’s tutorial says the menu is only visible to approved EvenHub developers, so sign up for EvenHub first if you don’t see it.
Add agent: a name, your server's URL (the full path) and a token. These are example values.
Tap the agent so it is selected. Saving alone doesn't select it.
What the app sends and expects
The app makes one HTTP request for each thing you say:
URL: exactly what you entered in Agent Configuration, with nothing added. It can be any path. Even’s tutorial and OpenAI’s API use /v1/chat/completions.
Request: a POST with an OpenAI-style chat-completions JSON body. model is always openclaw. messages holds only the latest thing you said, with the wake word removed. There is no streaming.
Auth: your token, as Authorization: Bearer <token>.
Reply: JSON. The app shows choices[0].message.content.
A captured request:
{
  "model": "openclaw",
  "messages": [{
    "role": "user",
    "content":
      "What's on my calendar?"
  }]
}
My server replies with the full standard shape. I haven’t tried a smaller one:
Even documents the feature in its own OpenClaw tutorial, and others have built adapters for it, like kucau0901’s even-g2-agent-adapter. This is how mine works, and the sample has backends for any OpenAI-compatible API, including a local model, and for Claude Code:
It listens on /v1/chat/completions and checks the bearer token.
It answers each request once. The app sends every request twice, about 5 milliseconds apart, so identical requests share one answer.
It keeps replies to plain text under 350 characters. Others report the lens renders roughly 400 to 500 characters and drops glyphs it can’t draw, so 350 is my margin.
After 25 seconds it sends a holding reply, and returns the finished answer when the same question comes in again. The 25 seconds is my choice, not a limit I measured. On mine, long jobs finish in the background and the result lands on Telegram.
The full server: server.mjs▾
#!/usr/bin/env node
// Use your own AI agent as the assistant on Even Realities G2 glasses.
// The Even app POSTs each spoken request to a URL you configure, in OpenAI
// chat-completions format. This server answers it with whatever backend you pick.
//
//   TOKEN=secret BACKEND=echo node server.mjs
import { createServer as createHttpServer } from 'node:http';
import { timingSafeEqual } from 'node:crypto';
import { pathToFileURL } from 'node:url';

const PATH = '/v1/chat/completions';
const SYSTEM_PROMPT =
  'You are answering on smart glasses with a tiny display. Reply in plain text, ' +
  'no markdown, no lists, under 300 characters.';

/** The app sends only the latest utterance, but take the last user message to be safe. */
export function lastUserText(body) {
  const messages = Array.isArray(body?.messages) ? body.messages : [];
  for (let i = messages.length - 1; i >= 0; i--) {
    const m = messages[i];
    if (m?.role !== 'user') continue;
    if (typeof m.content === 'string') return m.content.trim();
    if (Array.isArray(m.content)) {
      return m.content.map((p) => (typeof p === 'string' ? p : p?.text ?? '')).join(' ').trim();
    }
  }
  return '';
}

/** The lens drops unsupported glyphs and stops rendering after roughly 400 to 500 characters. */
export function fitToLens(text, maxChars = 350) {
  let t = String(text)
    .replace(/```[\s\S]*?```/g, ' ')
    .replace(/[*_`#>]+/g, '')
    .replace(/\[([^\]]+)\]\([^)]*\)/g, '$1')
    .replace(/\s+/g, ' ')
    .trim();
  if (t.length <= maxChars) return t;
  t = t.slice(0, maxChars);
  const end = Math.max(t.lastIndexOf('. '), t.lastIndexOf('? '), t.lastIndexOf('! '));
  return end > maxChars * 0.5 ? t.slice(0, end + 1) : t.replace(/\s+\S*$/, '') + '...';
}

function tokenOk(header, token) {
  const given = Buffer.from((header ?? '').replace(/^Bearer\s+/i, ''));
  const want = Buffer.from(token);
  return given.length === want.length && timingSafeEqual(given, want);
}

export function createServer({
  token,
  backend,
  maxChars = 350,
  replyTimeoutMs = 25000,
  dedupeWindowMs = 6000,
  log = () => {},
}) {
  if (!token) throw new Error('token is required');
  // The Even app fires every request twice about 5 ms apart. Share one answer.
  const recent = new Map(); // text -> { at, promise }

  // A slow agent gets a holding reply now; when it finishes, asking the same thing again returns it.
  const finished = new Map(); // text -> answer that arrived after the holding reply

  function answer(text) {
    if (finished.has(text)) {
      const done = finished.get(text);
      finished.delete(text);
      return Promise.resolve(done);
    }
    const hit = recent.get(text);
    if (hit && Date.now() - hit.at < dedupeWindowMs) {
      log(`dedupe "${text}"`);
      return hit.promise;
    }
    let timedOut = false;
    const work = Promise.resolve(backend(text, { systemPrompt: SYSTEM_PROMPT }))
      .then((r) => fitToLens(r, maxChars))
      .catch((e) => {
        log(`backend error: ${e.message}`);
        return 'Sorry, my agent hit an error.';
      })
      .then((r) => {
        if (timedOut) finished.set(text, r);
        return r;
      });
    let timer;
    const slow = new Promise((resolve) => {
      timer = setTimeout(() => {
        timedOut = true;
        resolve('Still working on it. Ask me again in a moment.');
      }, replyTimeoutMs);
    });
    const promise = Promise.race([work, slow]).finally(() => clearTimeout(timer));
    recent.set(text, { at: Date.now(), promise });
    for (const [k, v] of recent) if (Date.now() - v.at > dedupeWindowMs * 4) recent.delete(k);
    return promise;
  }

  return createHttpServer(async (req, res) => {
    const send = (code, obj) => {
      const payload = JSON.stringify(obj);
      res.writeHead(code, { 'Content-Type': 'application/json', 'Content-Length': Buffer.byteLength(payload) });
      res.end(payload);
    };
    if (req.method === 'GET' && req.url === '/health') return send(200, { ok: true });
    if (req.method !== 'POST' || req.url !== PATH) return send(404, { error: 'not found' });
    if (!tokenOk(req.headers.authorization, token)) return send(401, { error: 'bad token' });

    let raw = '';
    for await (const chunk of req) raw += chunk;
    let body;
    try { body = JSON.parse(raw); } catch { return send(400, { error: 'invalid JSON' }); }
    const text = lastUserText(body);
    if (!text) return send(400, { error: 'no user message' });

    log(`request "${text}"`);
    const content = await answer(text);
    return send(200, {
      id: `chatcmpl-${Date.now()}`,
      object: 'chat.completion',
      created: Math.floor(Date.now() / 1000),
      model: body.model ?? 'openclaw',
      choices: [{ index: 0, message: { role: 'assistant', content }, finish_reason: 'stop' }],
      usage: { prompt_tokens: 0, completion_tokens: 0, total_tokens: 0 },
    });
  });
}

async function main() {
  const { TOKEN, PORT = '3458', BIND = '127.0.0.1', BACKEND = 'echo', MAX_CHARS = '350' } = process.env;
  if (!TOKEN) {
    console.error('Set TOKEN to the same value you type into the Even app as the API key.');
    process.exit(1);
  }
  const backend = (await import(`./backends/${BACKEND}.mjs`)).default;
  const server = createServer({
    token: TOKEN,
    backend,
    maxChars: Number(MAX_CHARS),
    log: (m) => console.log(new Date().toISOString(), m),
  });
  server.listen(Number(PORT), BIND, () =>
    console.log(`Listening on http://${BIND}:${PORT}${PATH} (backend: ${BACKEND})`),
  );
}

if (import.meta.url === pathToFileURL(process.argv[1]).href) main();
Where it runs
The phone calls your URL directly, so use the same Wi-Fi, a tunnel, or Tailscale on both devices. Even’s tutorial warns against exposing an agent with access to your machine to the public internet without protection, and I agree. Mine runs on a small always-on Linux server on my Tailscale network.